You search your own docs for an error code and the AI hands you a different one. You ask for the v2.3 release notes and v3.2 shows up. The search is not broken in the usual sense: it is doing exactly what a meaning-based search does.
The symptom
Search for ERR_4521. Get ERR_4512.
You get its lookalike. To the model, they mean the same thing.Near-identical strings get near-identical embeddings, so cosine ranking confuses them.
Text version
- The symptom: Search for ERR_4521. Get ERR_4512.
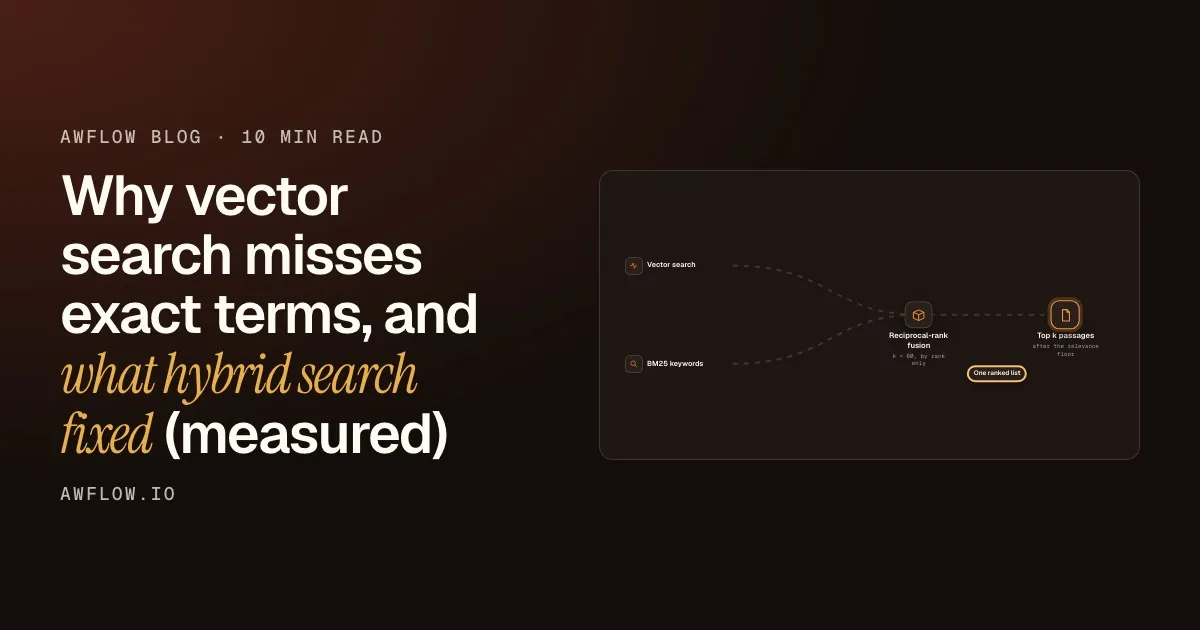
We fixed this in our in-browser knowledge bases with hybrid search: BM25 keywords plus vectors, fused with reciprocal-rank fusion. This post covers how it works, the numbers we measured, a database gotcha, and a second bug that made small collections return nothing.
This is part 2. Part 1, We rebuilt RAG in a browser tab, tells the whole rebuild, starting with the bug where every vector was empty.
Why vectors blur exact strings
To a sentence-embedding model, near-identical strings mean near-identical things. That’s exactly what you don’t want for error codes, SKUs, versions, names and IDs. Meaning is the right tool for “how do I get my money back?” and the wrong one for ERR_4521.
The setup, all on the user’s machine:
- Embeddings:
all-MiniLM-L6-v2(384-d), running in a Web Worker - Store: SurrealDB 2.x compiled to WebAssembly, on IndexedDB (how that works: WebAssembly, explained)
- Indexes per chunk table: HNSW (cosine) for vectors, and a BM25 full-text index with a simple analyzer (lowercase, ascii, English snowball stemming)
We added BM25 keyword search next to vector search.
A classic way to rank documents by the exact words they share with your question, giving rare words more weight.
A term-frequency / inverse-document-frequency score summed over query terms, with document-length normalisation. Here it runs on a SurrealDB full-text index.
What it does: it counts matching words, weighted by rarity.BM25 is a sum over terms, which matters for the gotcha below.
Text version
- We added BM25 keyword search next to vector search.
- BM25: A classic way to rank documents by the exact words they share with your question, giving rare words more weight. A term-frequency / inverse-document-frequency score summed over query terms, with document-length normalisation. Here it runs on a SurrealDB full-text index. (Keyword search, Full-text index, Embeddings)
How the hybrid query works
The query runs two searches and fuses their ranked lists:
query ─┬─ embed ───────────────► vector list (fetchK nearest)
       └─ keyword terms ───────► BM25 list   (fetchK best)
                                     │
                     reciprocal-rank fusion (k = 60)
                                     │
                           (optional rerank)
                                     │
top kOne list comes out, filtered by real relevance.The floor applies to cosine similarity, and real keyword matches pass on their own.
Text version
- Vector search: fetchK nearest · BM25 keywords: fetchK best matches
- fetchK nearest + fetchK best matches → Reciprocal-rank fusion
- Reciprocal-rank fusion → Top k passages: One ranked list
Two lists for one question
The query is split into keyword terms: words with punctuation trimmed, English, French and German stopwords dropped, at most 12 terms. Each list fetches fetchK = min(200, max(k, 4k, 20)) candidates, so fusion has enough overlap to work with.
Fused by rank, not by score
Each document scores Σ 1 / (60 + rank) over the lists it appears in, normalised to 0..1. RRF ignores the raw scores, which is the point: BM25 scores and cosine similarities aren’t on the same scale, and RRF never has to compare them.
Then a relevance floor
Only passages that are actually relevant make the final top k. How that floor works is the subtle part, below.
Here’s that subtlety. Because the fused score is rank-based, you can’t put a “minimum relevance” cut-off on it.
Put a minimum-score cut-off on the fused result.
Rank 1 of a terrible list is still rank 1. Put the floor on cosine similarity, and let real keyword matches through.
But the fused score only knows ranks.Floor on each hit's cosine similarity (computed from the stored vector for keyword-only hits); a hit with BM25 > 0 and more than half the terms present counts as relevant by itself.
Text version
- Put a minimum-score cut-off on the fused result.
- Rank 1 of a terrible list is still rank 1. Put the floor on cosine similarity, and let real keyword matches through.
So we apply the floor to each hit’s cosine similarity (computed from the stored vector for keyword-only hits). A hit also counts as relevant by itself if it’s a real keyword match: BM25 > 0 and more than half of the query terms present. That way an exact code survives even when its embedding scores below the cut-off.
The SurrealDB gotcha: @@ is AND-only
SurrealDB 2.x’s full-text match operator only matches rows that contain all the tokens, and there’s no OR form. A 6-word question would match almost nothing.
The workaround: give each term its own match reference and sum the scores.
SELECT id, text, metadata, vector,
  (math::max([search::score(1) ?? 0, 0])
 + math::max([search::score(2) ?? 0, 0])
 + math::max([search::score(3) ?? 0, 0])) AS bm25
FROM type::table($table)
WHERE (text @1@ $t1 OR text @2@ $t2 OR text @3@ $t3)
  AND knowledge_id = $knowledgeId
ORDER BY bm25 DESC
LIMIT $k;
Summing is legitimate, because BM25 is itself a sum over terms. A missing term adds 0. A term that appears in almost every row can score below 0, so each score is clamped at 0. A nice side effect: a term with several tokens (ERR_4521, v2.3, e-mail) still needs all of its own tokens, which keeps codes precise.
The numbers
Our test set: 20 questions over 27 documents, deliberately full of near-duplicate error codes and version families. 12 questions ask for an exact term, 8 are paraphrases. With the real MiniLM model:
| Vector | Hybrid | Hybrid + rerank | |
|---|---|---|---|
| recall@1, all | 0.90 | 0.95 | 0.95 |
| recall@3 / @5, all | 1.00 / 1.00 | 1.00 / 1.00 | 1.00 / 1.00 |
| recall@1, exact terms | 0.83 | 0.92 | 1.00 |
| recall@1, paraphrases | 1.00 | 1.00 | 0.88 |
Turn the dial to see what each step bought and what it cost, using the recall@1 figures from the table:
Opt-in: Rerank on this device
Rerank: fixes the last code, loses a paraphrase. Opt-in.Cross-encoder ms-marco-MiniLM-L-6-v2 on device: exact 1.00, paraphrase 0.88, all 0.95.
Text version
- Ranking method Vector: Exact terms @1 0.83 · Paraphrases @1 1.00 · All @1 0.90 · The old default
- Ranking method Hybrid: Exact terms @1 0.92 · Paraphrases @1 1.00 · All @1 0.95 · The default now
- Ranking method + rerank: Exact terms @1 1.00 · Paraphrases @1 0.88 · All @1 0.95 · Opt-in: Rerank on this device
What we took from it:
- Hybrid never did worse than vector, and it fixed exact-term misses at rank 1. It’s the default now.
- The cross-encoder rerank (
ms-marco-MiniLM-L-6-v2, on device) fixed the last exact-term miss but lost a paraphrase. It’s an opt-in switch (“Rerank on this device”), not the default. - At @3 everything is already perfect on this set. Rank 1 matters most when only the top few passages fit in a small model’s context.
To be clear, this is 20 questions, not a benchmark. We kept it because it encodes the failures our users actually hit, and it runs in CI with a synthetic embedder. That synthetic embedder is much weaker (vector 0.35 → hybrid 0.90 at @1), which makes it a good canary when the keyword path regresses.
The second bug: filtered KNN that returns nothing
All knowledge bases that use the same embedding model share one table, filtered by knowledge_id. In SurrealDB 2.x, the bare KNN operator <|k|> on an HNSW index runs a top-k over the whole table and filters afterwards.
So imagine a 60-chunk knowledge base next to a 2,940-chunk one in the same table:
Then it filters, and nothing is left.Post-filtering a global top-k returns 0 rows when the big KB holds every neighbour.
Text version
- Search the 60-chunk KB: top 4, please
- Top 4 of the whole table: can all come from the big KB
- Filter by knowledge_id: 0 hits
Ask for the top 4, and the global top-4 can be all from the big one. Filter to the small one, and you get 0 hits.
The fix has three parts:
- Filter during the walk. The
<|K,ef|>form applies theknowledge_idcondition while it traverses the HNSW graph. - Over-fetch.
fetchK = min(max(3k, k+8), 200), with the search effortefscaled to it (64 to 800). - An exact fallback. If the approximate query errors or returns fewer than k rows, run an exact filter-first scan:
WHERE knowledge_id = $kb, cosine similarity,ORDER BY,LIMIT k.
We measured both paths on 3,000 × 384-d vectors: the approximate query takes about 14 ms, the exact scan 160 to 556 ms depending on knowledge base size.
Search 3,000 × 384-d vectors
The approximate path wins by far, so exact is only the fallback.The exact scan runs only when the approximate query errors or returns fewer than k rows.
Text version
- Search 3,000 × 384-d vectors
- Approximate (HNSW): 14 ms · Exact scan, fastest case: 160 ms · Exact scan, slowest case: 556 ms
- exact = safety net
So the fallback is a safety net, not the main path. A low ef (40) had poor recall on the big knowledge base, hence the scaling.
Test this in your own stack: create a tiny collection next to a big one in the same index, and query the tiny one. Many vector stores post-filter by default.
Takeaways
Seven things to check
- Embeddings blur exact strings: add keywords
- Fuse by rank (RRF), not by raw score
- Floor on similarity, not on the fused score
- Check if your full-text operator is AND-only
- Measure rerankers on paraphrases too
- Test a small collection next to a big one
- Keep a small eval of your real failures in CI
Keep the eval. It catches regressions.20 questions, run in CI with a synthetic embedder as a canary.
Text version
- Seven things to check
- Embeddings blur exact strings: add keywords
- Fuse by rank (RRF), not by raw score
- Floor on similarity, not on the fused score
- Check if your full-text operator is AND-only
- Measure rerankers on paraphrases too
- Test a small collection next to a big one
- Keep a small eval of your real failures in CI
These questions apply to any RAG stack, whatever store you use. If your models run on device as ours do, running an LLM in the browser explains the runtimes.
Have you measured a reranker that hurt? I’d like to know if paraphrases were the casualty for you too.
The knowledge bases described here are part of AWFlow, a browser extension for workflows and AI agents that runs locally.